PR review time (also called review turnaround) is how long a pull request waits for meaningful review attention. Teams mix it up with PR cycle time or time-to-merge — then optimize the wrong slice of the funnel.
PR review time vs PR cycle time
- PR review time — ready-for-review → first substantive human response (not a bot ACK alone).
- PR cycle time — usually first commit (or PR open) → merge; includes coding, waiting, CI, and rework.
- Time to merge — PR open → merge; useful, but often dominated by waiting-for-review.
If waiting-for-review is most of your time-to-merge, you have a review bottleneck, not a “developers are slow” problem. Cutting PR cycle time without measuring PR review time is how teams buy faster CI and still ship late.
Published benchmarks (with sources)
- Google eng-practices — prefer responding within one business day.
- Meta Engineering — slow reviews correlate with engineer dissatisfaction; they invested in speeding review.
- Vendor research (e.g. Graphite on median time-to-merge) is useful context, but compare like-for-like metrics — merge time ≠ review turnaround.
For a small team, a practical target is: most PRs get a first human look the same day they are marked ready.
Measure yours with free tools
You do not need a fancy dashboard on day one. Export PR timestamps
from GitHub (UI insights, API, or
gh pr list / gh api), then compute:
- Time ready → first human comment/review
- Time ready → approve
- Time open → merge
Chart medians weekly. Ignore vanity averages ruined by one abandoned PR.
How to reduce PR review time: find your bottleneck
Every team’s review pipeline is different. Before you buy another tool, write down where the PR actually sits: waiting for CI, waiting for a human, waiting for the author to reply, or waiting for the review bot to finish. Most teams that already have an automated first pass discover the bottleneck is the bot — not motivation.
Review bots are not equal. Some take minutes on a mid-size diff because the model is slow, the prompt is a novel, or the job is serial. Mergestorm’s Vortex is built to be fast without degrading quality: a first pass that lands while the author is still in context. Cyclone patches mechanical fixes. Tempest is the deeper pass on risky changes. Maelstrom is a plan name, not an agent.
Review bots and PR review time
If you are wiring your own review loop, three knobs dominate how long the bot takes:
- Model and provider. Tokens per second matter. A “smarter” model that streams slowly can add more PR review time than it saves in nits caught.
- How deep the review is. Extra thinking, long chain-of-thought, and “find every race condition” prompts burn latency. That is a tradeoff, not a free upgrade.
- How big the PR is. The same bot on a 20-file monster will feel broken even if tok/s is fine.
Fast reviews mean the bot only got through so much. A 20-second pass will not be a Tempest-depth audit. Say that out loud so the team does not treat a quick first look as a merge stamp. The other way to keep PR review time down without going shallow is parallel specialists — Vortex-style: several focused reviewers on the same diff at once, instead of one agent walking the whole tree in a single file.
Split fat PRs to reduce PR review time
One fat PR with 20 file changes is queue poison for humans and bots. Open a stack of five PRs with about four files each. Each review is shorter, more detailed, and cheaper to re-run. When you integrate the stack, you can run another pass on the combined surface if you want — that second pass is optional, and it is still faster than asking anyone to start a 20-file monster.
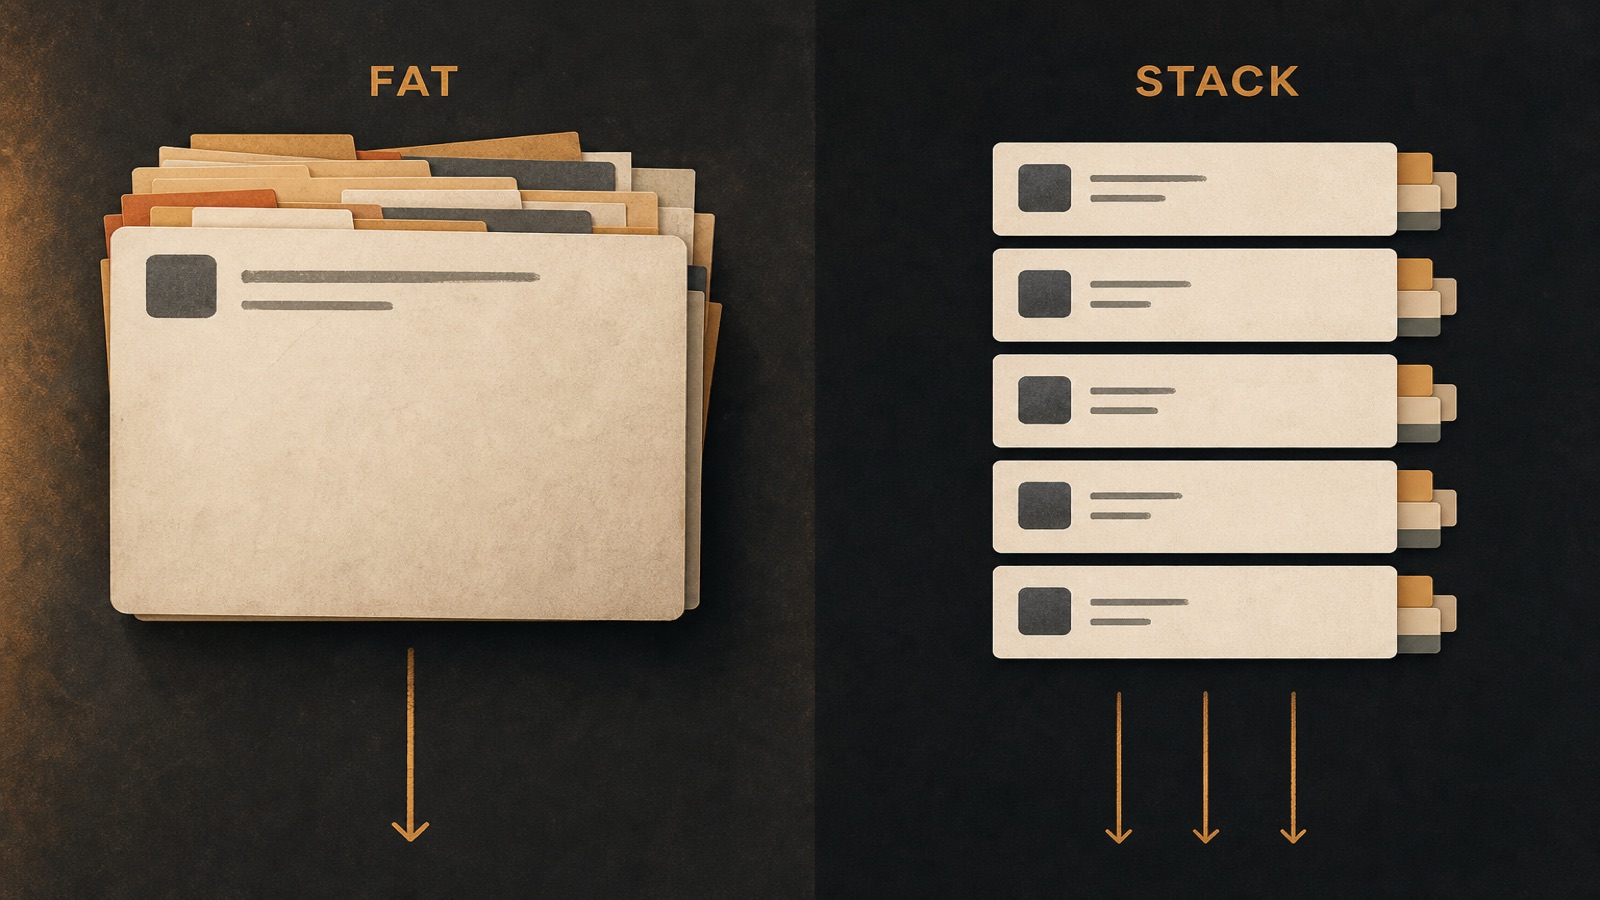
Smaller diffs are also how humans start reviews as a break instead of a project. More on that in how to get pull requests reviewed faster.
Four levers that actually move turnaround
- Size — stack focused PRs instead of one fat diff.
- CI speed — reviewers wait for green; flaky or slow checks pad the queue.
- Reviewer availability — ownership + SLA beat hope.
- Automation — a fast first pass (Vortex), optional patches (Cyclone), deep review on risk (Tempest). Parallel specialists beat one slow serial bot.
A 30-day improvement loop
Week 1: measure baseline. Week 2: enforce size + ownership. Week 3: add automated first review. Week 4: re-measure median turnaround and time-to-merge. Keep what moved the number; drop theater metrics.